CUA KnowledgeBench
Day-long knowledge work across 100+ applications, scored on private tasks.
- Models scored
- 10
- Runs per model
- 50
- Per run
- 12 hours
12-hour horizon
Published September 7, 2026.
- Claude Fable 5.124%
- Claude Fable 522%
- GPT-6 Astra20%
- Claude Opus 518%
- GPT-5.6 Sol16%
- Claude Sonnet 512%
- GPT-5.6 Terra8%
- Qwen3.8 Max6%
- Kimi K34%
- Gemini 3.8 Flash4%
Inside one environment
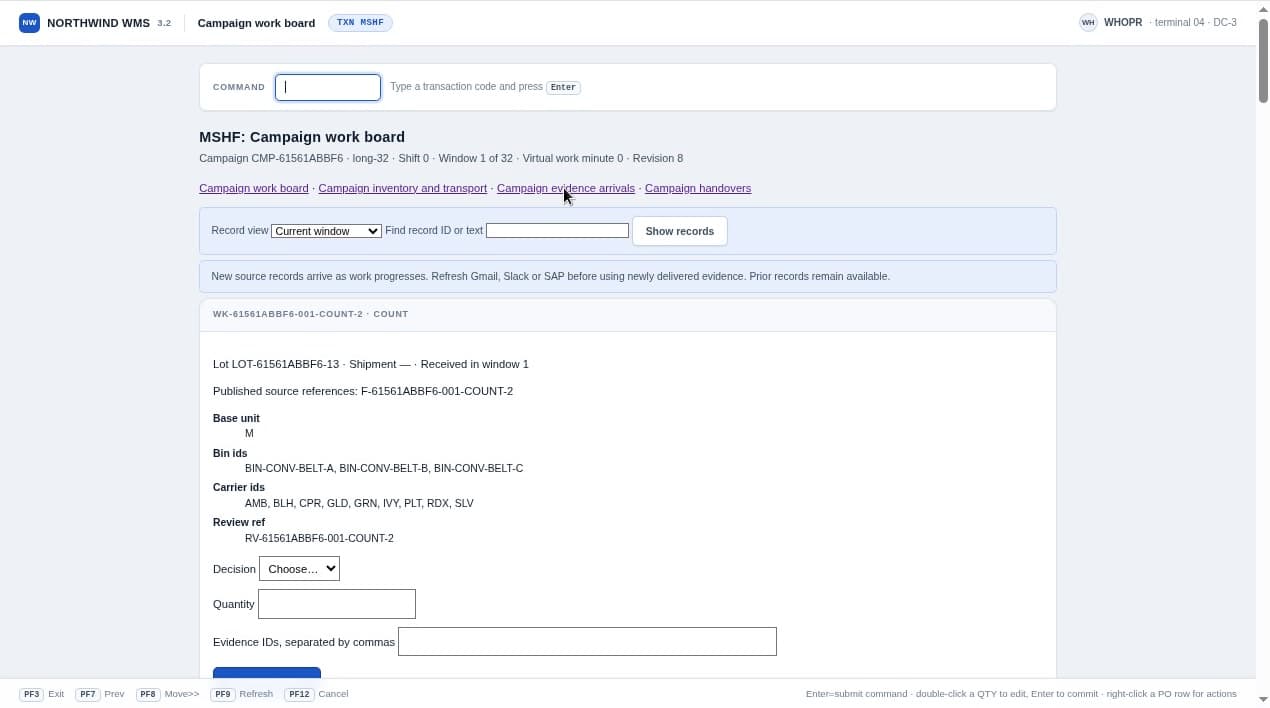
10 clips from one task attempt in Northwind WMS, 34 s each.
Longer horizons
- 1-day horizon
- Running. 6 tasks × 5 seeds, 24 hours per run.
- 3-day and 7-day horizons
- Coming soon.
How it’s measured
- Seeds
- A seed fixes the workspace state, the data in it and the timing of anything that changes during the run, so every model sees the same situations.
- Applications
- Real applications: communication, documents, spreadsheets, project and customer records, research and scheduling. Information is spread across them and changes during a run; the work is to keep it coherent. Not every application appears in every task.
- Budget
- A run that has not met the task’s check when its wall-clock budget ends is unsolved.
- Scoring
- Binary per run: the resulting documents, records and messages either meet the task’s check or do not. Success is runs solved over runs. Distinct tasks counts the tasks solved on at least one seed; solves per task is runs solved over distinct tasks.
- Steps and time
- Medians over solved runs only. Unsolved runs are excluded rather than counted at the budget, so a model with no solve shows neither.
- Resolution
- One run is 2 points of success rate on the 12-hour horizon, and the seeds of one task are not independent trials, so the results separate the top of the table from the bottom, not one row from the next.
- Not scored
- Grok 4.6, GPT-5.6 Luna, Muse Spark 1.3, Inkling and GLM 5.3 Flash. Their runs stopped in the early episodes after failures across tasks; a stopped model is left out rather than shown at 0%.
- Northwind WMS
- Northwind WMS is one of the environments in the suite. Records about lots, counts, carriers and storage arrive across a warehouse system, an ERP, team chat and mail, and every decision has to be recorded on the work board together with the evidence that supports it. The task runs across 32 work windows; as each window advances, new records are published and the ledgers move.
- Clips
- Each clip is an edited, time-condensed sequence of 40 consecutive saved screenshots from one task attempt, most held for under a second. Silent, no overlays, cropped to the application's own viewport without the browser's frame and address bar. The clips show how the environment is worked, not whether the task was solved.
- Evaluations
- New models are evaluated on the same suite by arrangement: founders@coasty.ai.
- Not published
- Task prompts, seeds, traces and per-task results. The suite stays private so results measure capability rather than recall.